Nathan Chen
Aspiring Data Scientist/Analyst with internship experience across SaaS, AI, and FoodTech. Recent Data Science graduate from UC Berkeley. Passionate about AI. US Citizen
View my LinkedIn Profile
Portfolio
4 selected projects in data science, machine learning, NLP and vibe coding
Work Experience
Data Science Intern @ Botrista (August 2025 - Present)
- Data team for office of the CEO.
Data Science Intern @ Splashtop (May 2024 - August 2024)
- Churn Prediction, Customer 360.
Data Science Intern @ Ozaru (February 2024 - May 2024)
- Skydeck Batch 17 Investor Exhibition.
Projects
LLM Persona Fine-Tuning: The “Wednesday Addams” Chatbot
Developed a reusable fine-tuning pipeline to adapt open-source Large Language Models (LLMs) to specific personas or domain requirements. Tested with GPT and Llama. As a proof of concept, I engineered a chatbot with the distinct personality of Wednesday Addams (Netflix). Since no public dataset existed, I manually curated and formatted a custom dialogue dataset from the show’s scripts. I utilized QLoRA (Quantized Low-Rank Adaptation) and 4-bit quantization to fine-tune the model efficiently on my laptop with minimal computational cost.


My Own Chess App
Developed a fully functional chess application with claude code to solve unlimited puzzles. Engineered the core game engine from scratch to enforce strict chess rules, including valid move generation, check/checkmate state detection, castling, and en passant. The frontend interface features interactive piece selection, legal move highlighting, a dynamic move history log, and a captured pieces tracker to provide a seamless user experience.
Gameplay Interface Demo:

Figure 1: Interactive Chess GUI and Move Logging


Ensemble Machine Learning for Sentiment Analysis on Amazon Reviews
Predicting customer satisfaction from text is a core challenge in e-commerce. In this project, I formulated star-rating prediction as a binary classification task, distinguishing 5-star reviews from lower ratings using Natural Language Processing (NLP). I created a custom ensemble (“Blending”) model that stacked Logistic Regression, CART, Random Forest, and Gradient Boosting classifiers, optimizing their weights via OLS regression to achieve a 16% accuracy improvement over the baseline.
Selected Project Figures:
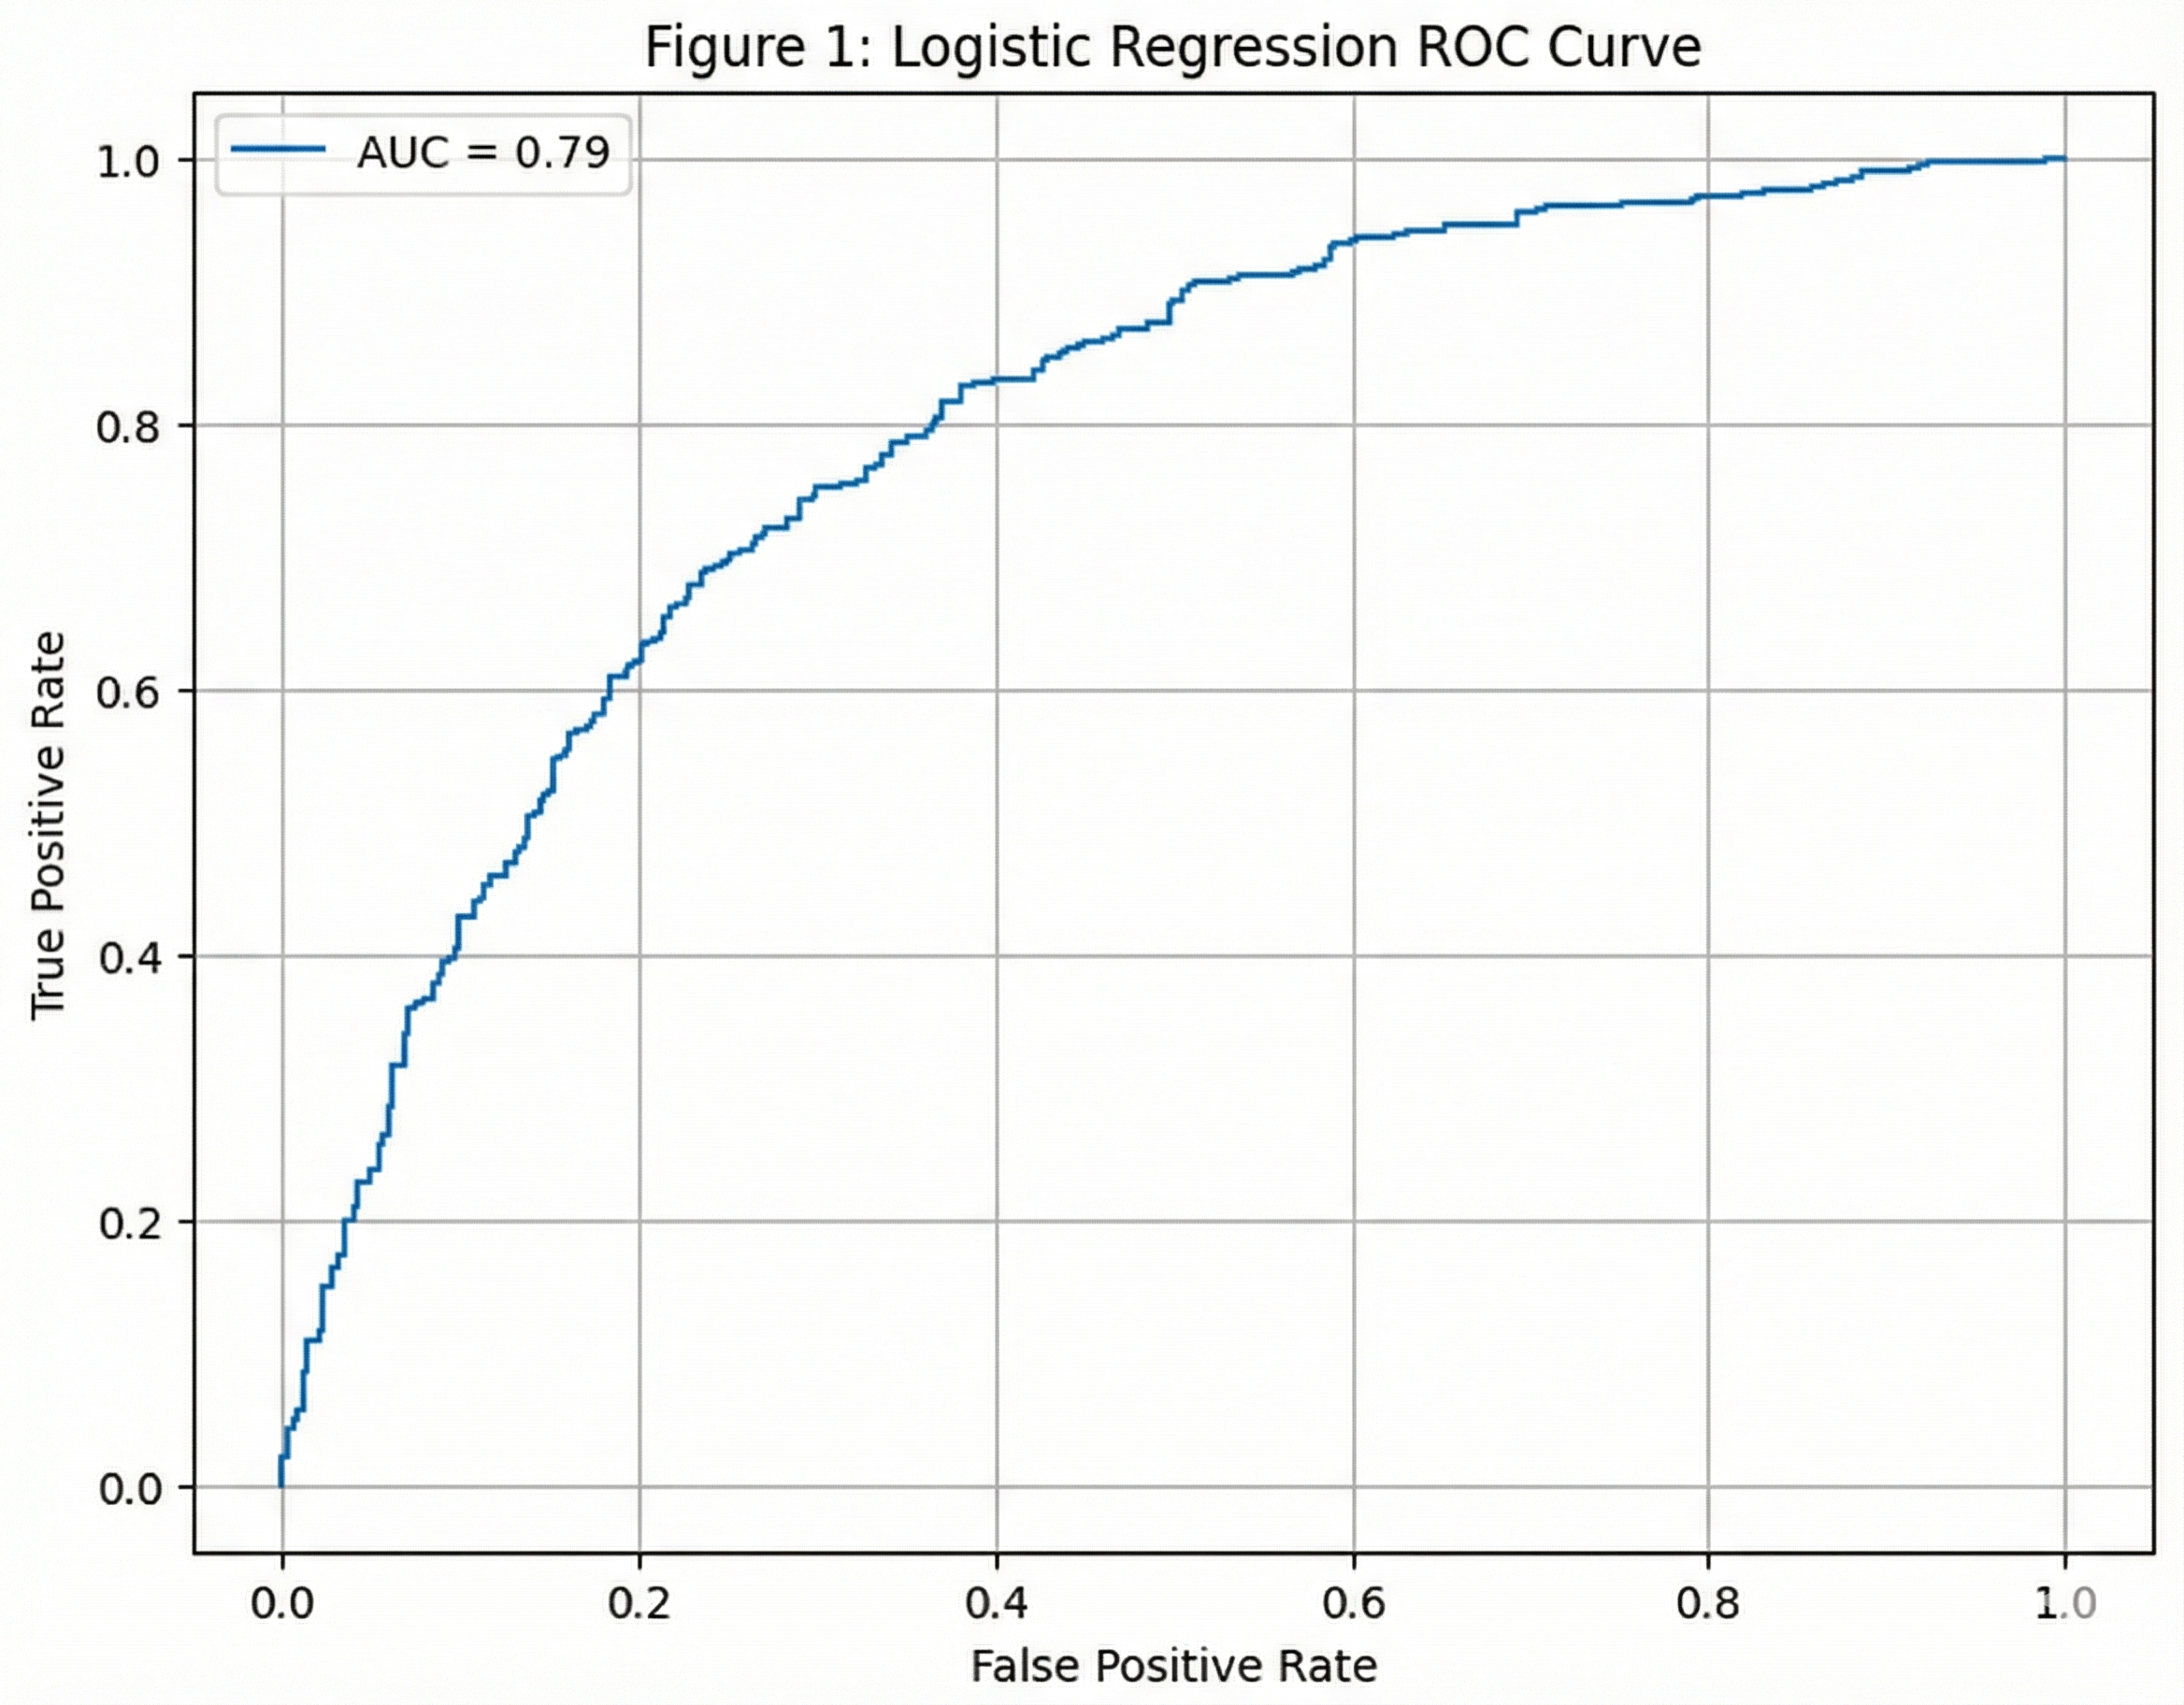
Figure 1. Logistic Regression ROC Curve |
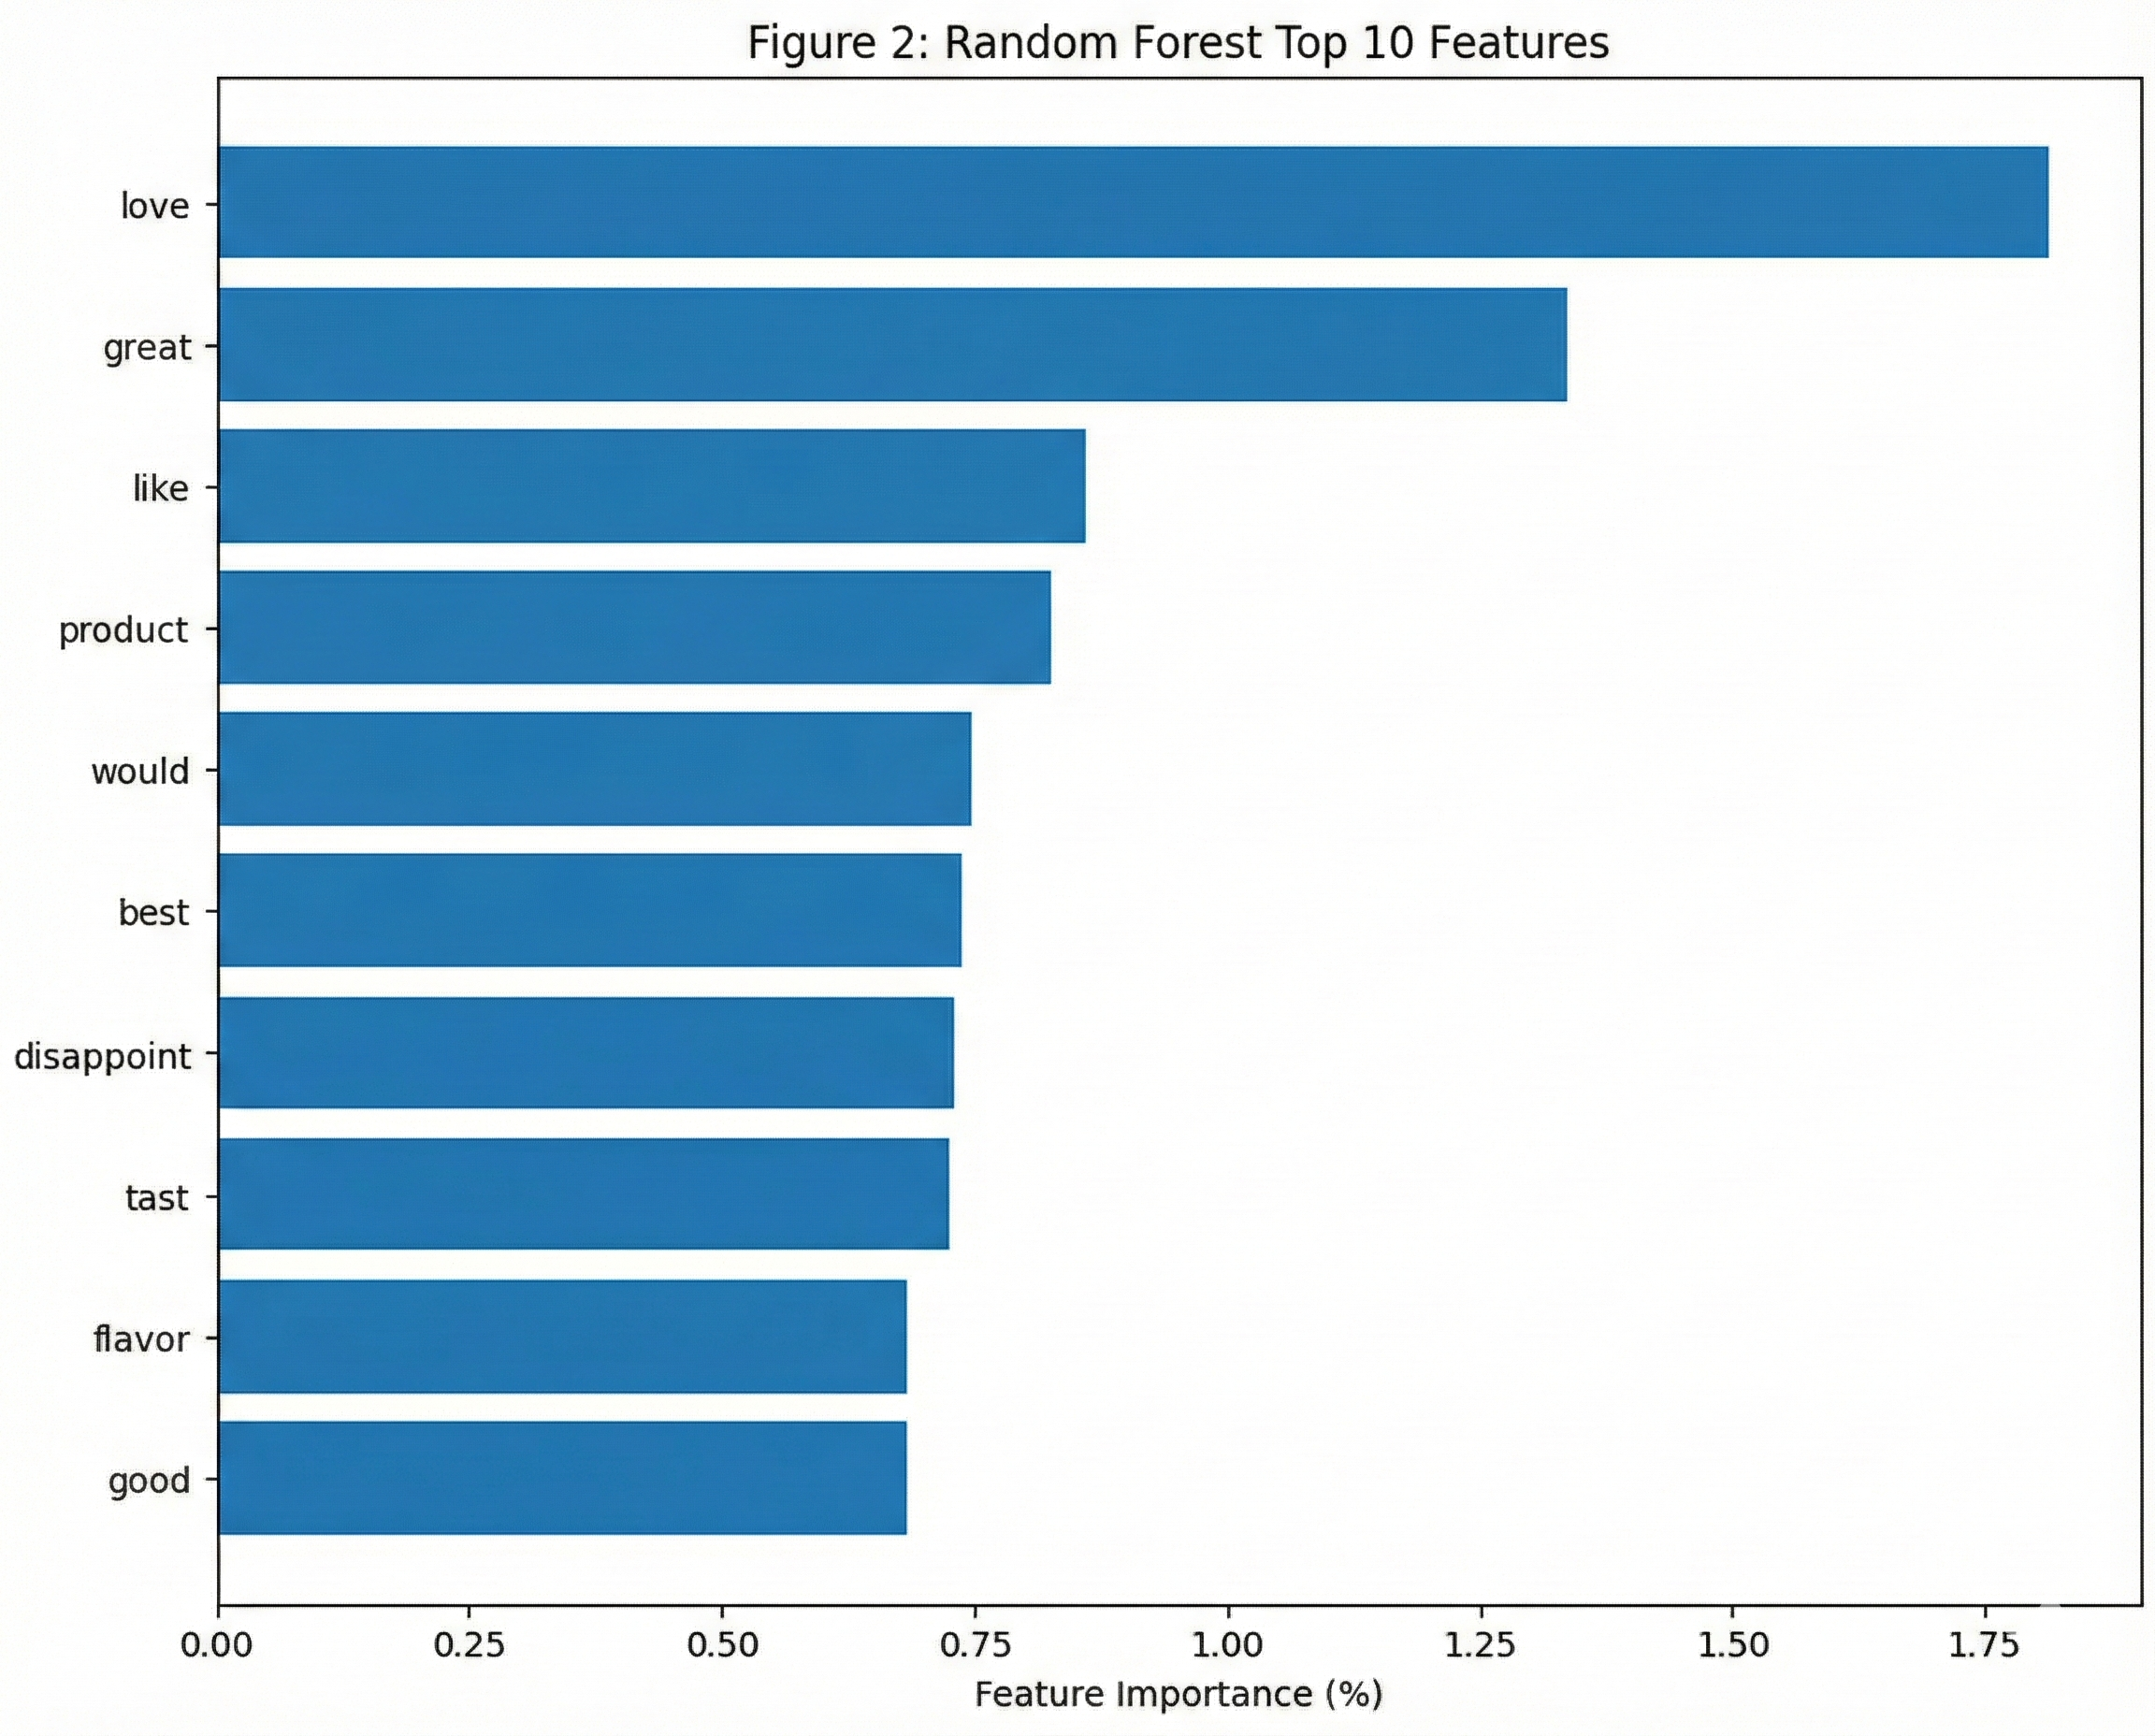
Figure 2: Random Forest Most Important Features |
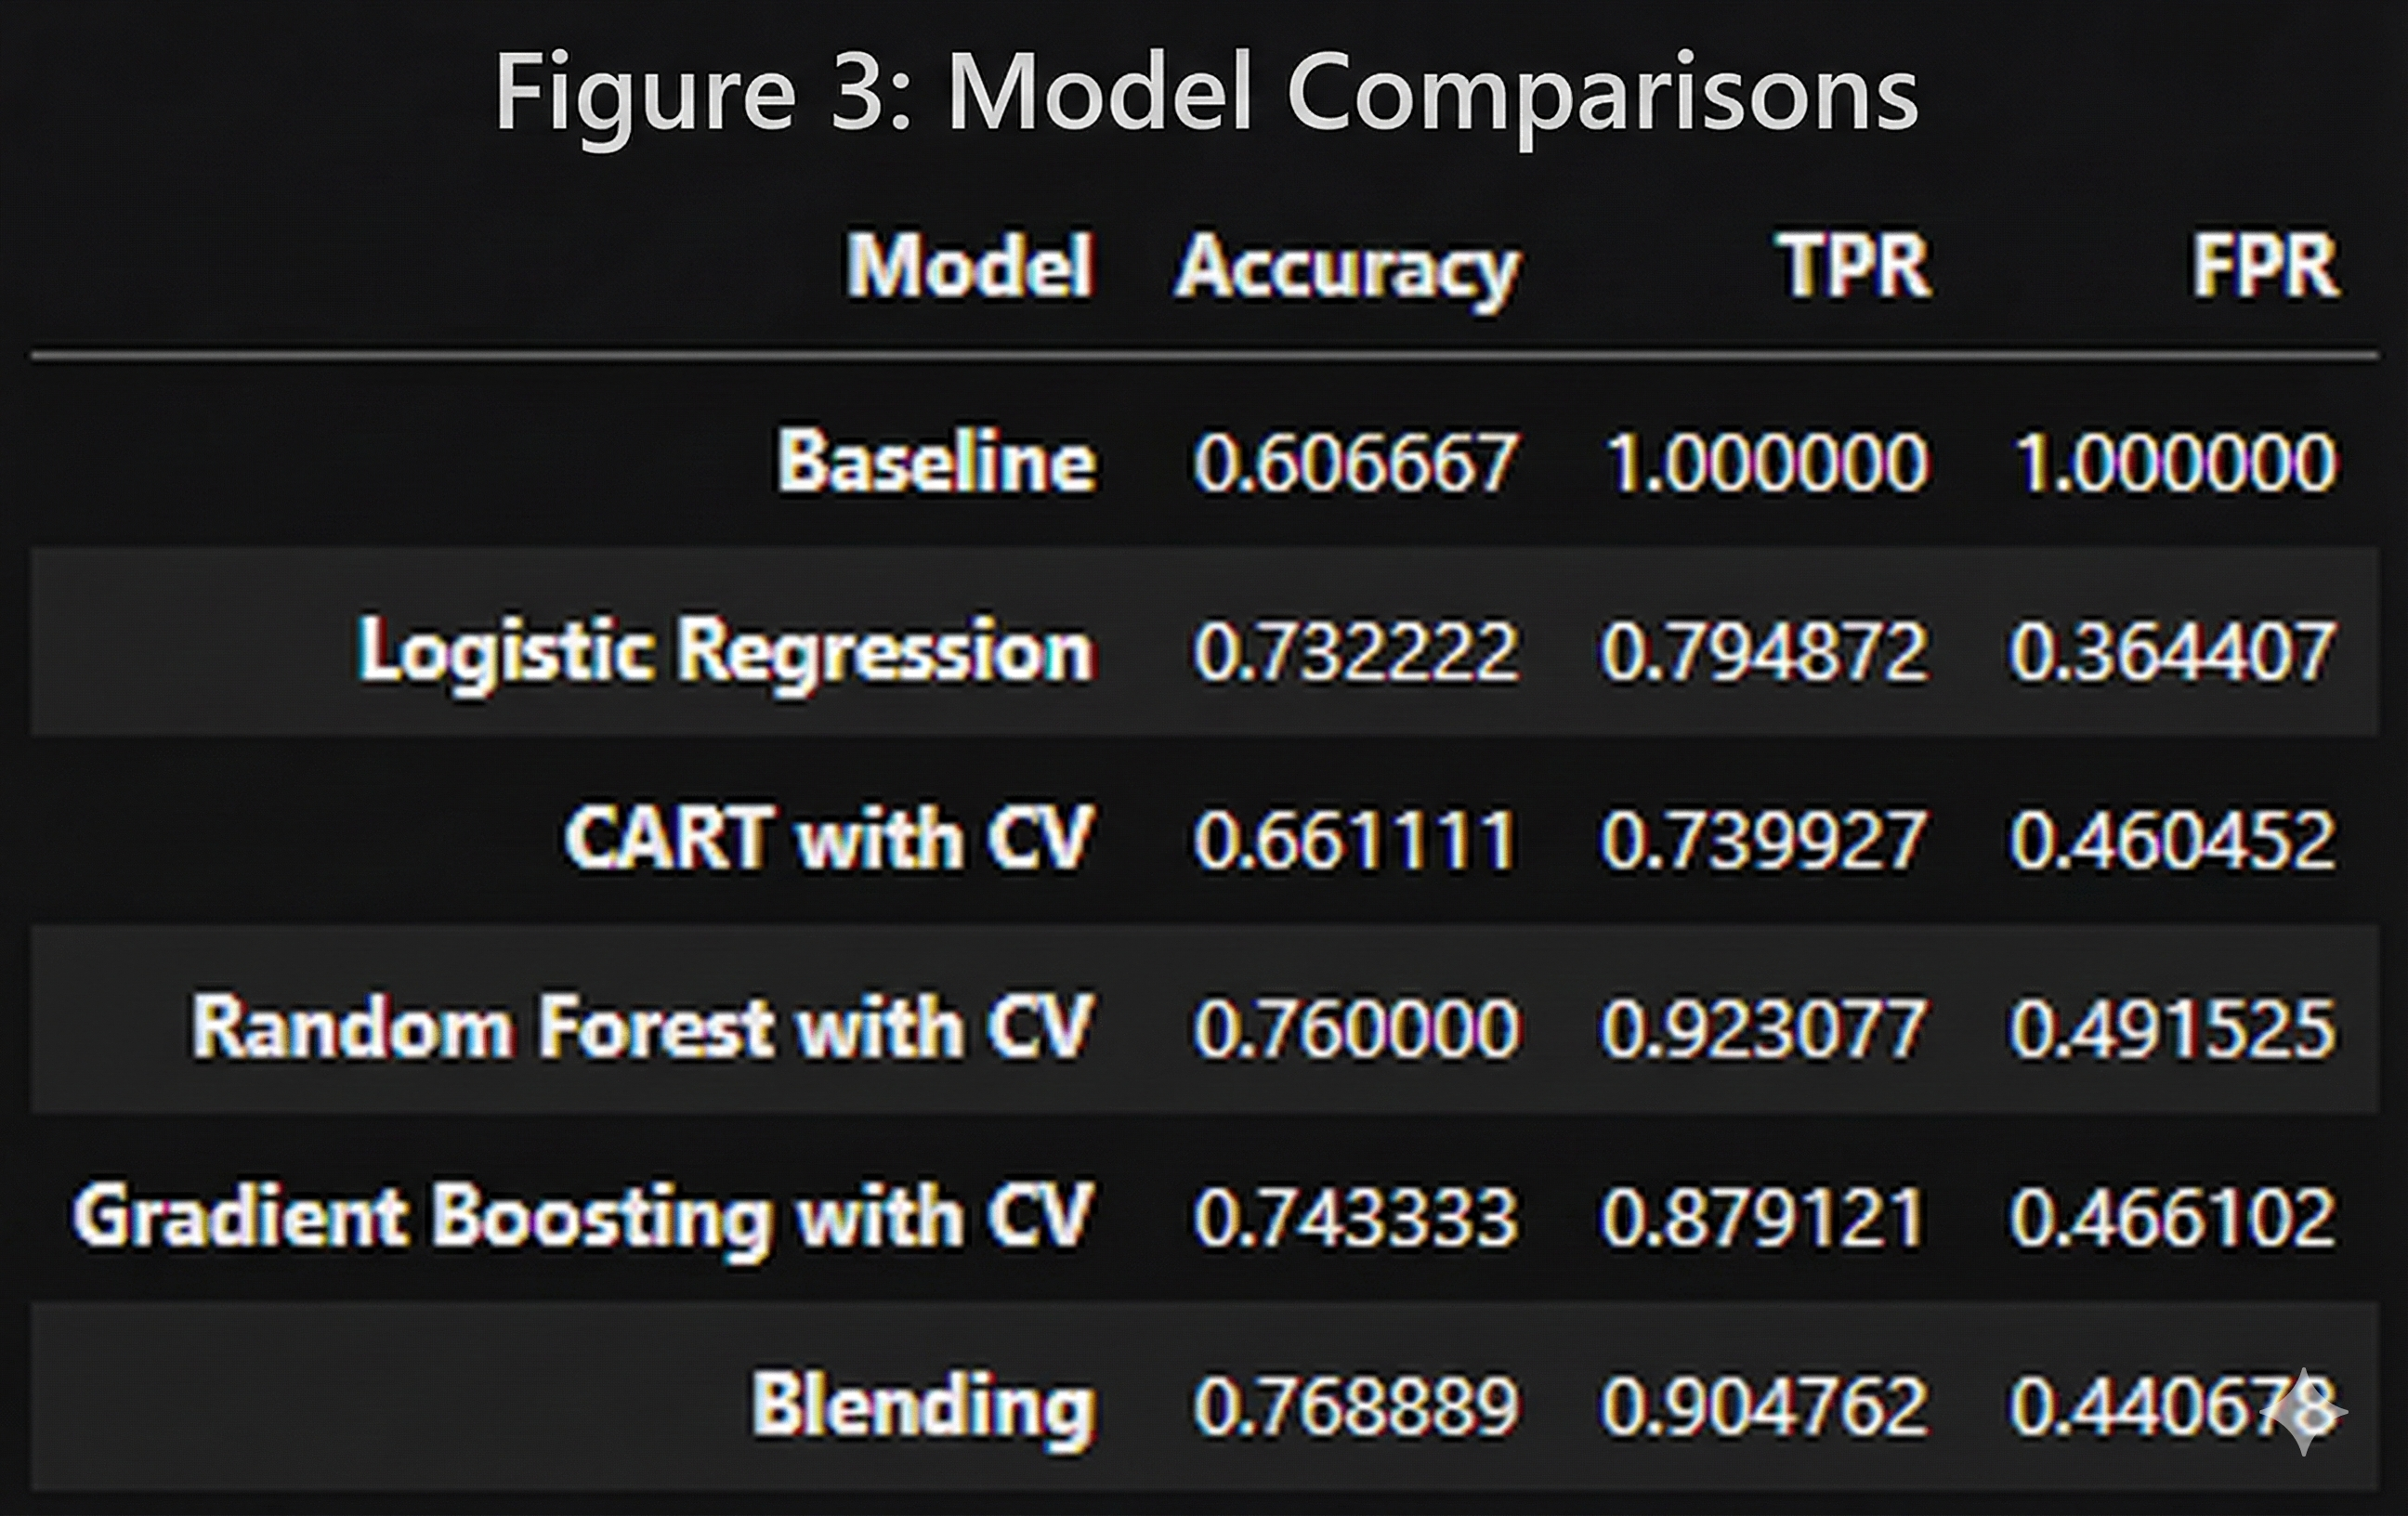
Figure 3: Model Comparison


7 Million Demand Elasticities: Visualizing the “Retail Apocalypse”
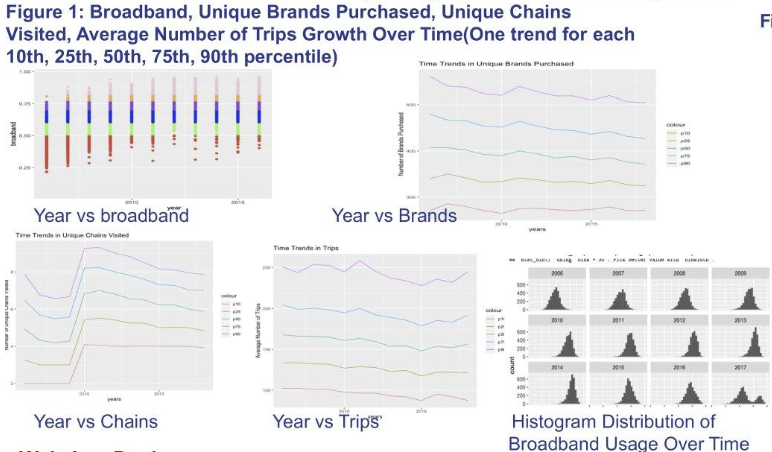
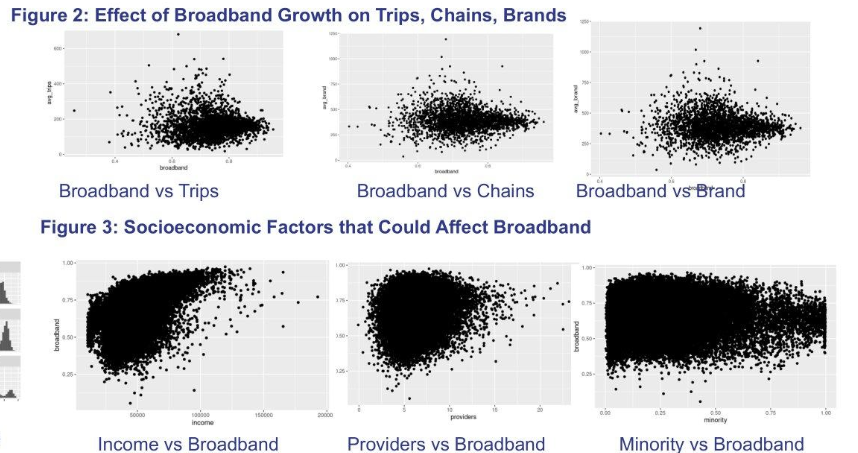
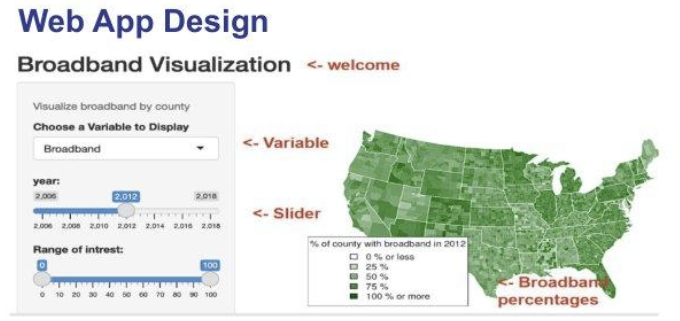
Collaborated with researchers from the San Francisco Fed and UChicago on the “Seven Million Demand Elasticities” (7MDE) project to investigate if broadband proliferation caused a decline in brick-and-mortar retail. Developed an interactive R Shiny dashboard to visualize over 7.5 million price elasticity estimates across 14,000 products. The analysis revealed no negative correlation between broadband usage and in-store consumer activity, challenging the retail apocalypse hypothesis.
Project Visualizations:


View Project Repository
View Official Poster